Summary: OpenTelemetry data pipeline tracing in Pixeltable is one trace per table operation. insert, collect, update, and the rest each root a span named pixeltable.<operation>. Under it sits the work the engine actually did: catalog and store steps, and, when you ask, a span per row, per file, and per UDF call. Every attribute the runtime records is prefixed pxt.: pxt.table and pxt.num_rows on an insert or update, pxt.tables and pxt.rows on a query such as collect, and pxt.column, pxt.udf_path, pxt.resource_pool, and pxt.retries on the UDF call. To trace multimodal pipelines, the same tree grows a span per downloaded file and, at the finest level, a span per iterator step such as a video frame. Point the exporter at Langfuse, Arize Phoenix, or MLflow. The catalog does not move with the trace.
This was checked on 2026-10-21 against Pixeltable 0.7.19 and opentelemetry-instrumentation-pixeltable 0.1.0 in that tag of the Pixeltable repo, with the Langfuse SDK 5.0.4, openinference-instrumentation-openai 0.1.65, openai 3.36.0, and the Anthropic Python SDK 2.0.0. The attribute names and span levels below are from that source, not from a vendor diagram.
One operation, one trace#
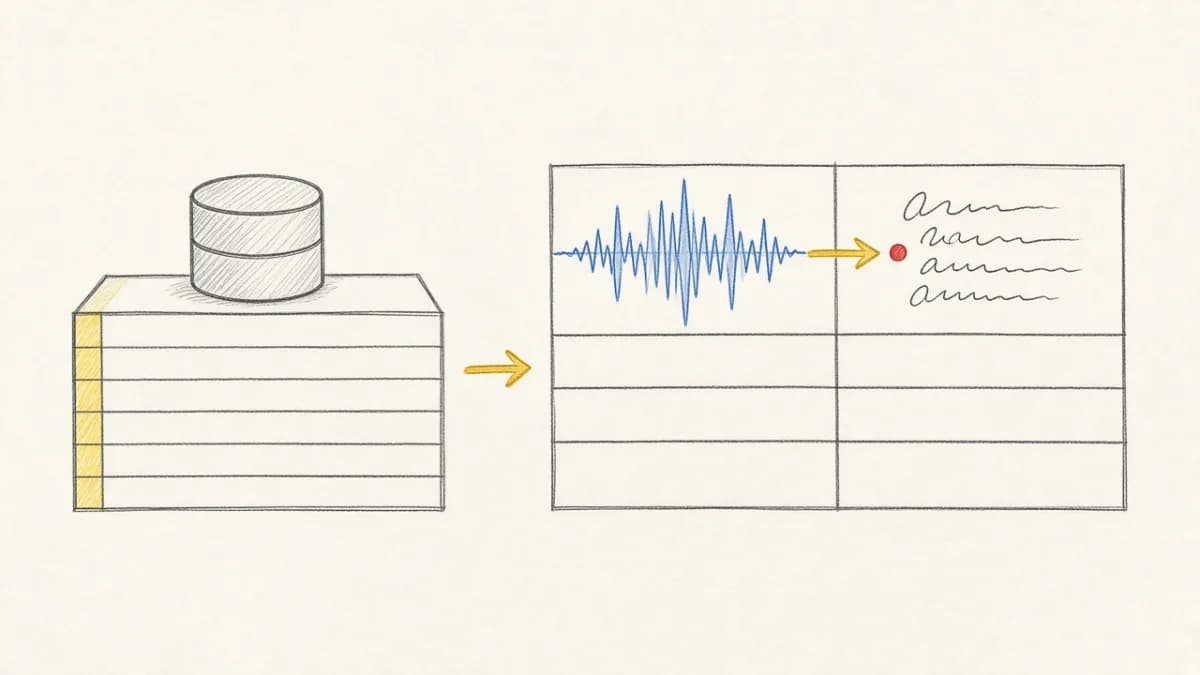
A declarative pipeline is a schema. The trace is the engine running that schema, not a DAG you assembled by hand. An insert of a row whose computed column calls a model looks like this:
Pixeltable's own spans say which operation, row, column, and UDF ran. They do not carry row ids or cell values. A provider UDF such as chat_completions records its token counts as a pixeltable.udf.tokens event (pxt.input_tokens, pxt.output_tokens) on the UDF span. An LLM instrumentor adds the model call as a child span, with the prompt, the completion, and its own token counts. The bridge sets the active OpenTelemetry context for every UDF call, including calls on its thread pools and its async scheduler, so the generation nests under pixeltable.udf.<name>.
The operation span is filled in when the operation finishes. From OpAttrs in pixeltable/telemetry_schemas.py, that includes pxt.table (the table name), pxt.table_id, pxt.path, pxt.version, pxt.num_rows, pxt.num_computed_values, and pxt.num_excs. The UDF span, from UdfCallAttrs, carries:
pxt.udf_path, the UDF's fully qualified name, so two functions with the same short name stay distinctpxt.column, the named column this call materializes, when it has onepxt.batch_size, on a batched callpxt.resource_poolandpxt.retries, on a call that went through a resource-pool scheduler.pxt.retriesis how many retries this attempt has already used, so the first try is 0
Why a computed column is hard to trace#
A computed column is not a function you call on the request thread. On insert, an expression-evaluation node hands cells to asyncio tasks. A call that names a resource pool waits in a scheduler: the pool that tracks provider usage retries up to 10 times, and the fixed request-rate scheduler retries up to 3. Media downloads and saves run on a thread pool. A video view's frame_iterator yields one row per frame, and each of those rows can call a model of its own.
A patch on openai that only sees the main thread misses the worker. A trace id you set around insert() does not follow a task unless something restores the context on that task. Pixeltable's telemetry does. Worker threads take a capture_context snapshot and restore_context it before the fetch or the save. Async tasks copy a context var at creation, so concurrent UDF calls keep their own ambient span. That is the mechanism that puts the generation under the UDF span instead of beside it.
Turn it on#
The bridge, opentelemetry-instrumentation-pixeltable, is opt-in. Pixeltable itself never imports OpenTelemetry. The extra declared in Pixeltable 0.7.19 is:
pixeltable[otel] pulls opentelemetry-instrumentation-pixeltable==0.1.0, the OpenTelemetry SDK, and the HTTP and gRPC exporters. openai is the client chat_completions calls; neither Pixeltable nor the instrumentor installs it. On 2026-10-21 the instrumentation package was not on PyPI yet, so the extra did not resolve. Until it is published, install the bridge from the same tag:
Call pxt_otel.init() once per process, before the first table operation. It reads the endpoint from the argument, then from db_exporter_otlp_endpoint on the [[pixeltable.database]] entry in pixeltable.toml, then from OTEL_EXPORTER_OTLP_ENDPOINT, then from the [otel] section of ~/.pixeltable/config.toml. With no endpoint and no provider your application already configured, instrumentation stays inert and exports nothing. A second init() raises, so a kernel that already called it with no endpoint has to be restarted. The headers come from OTEL_EXPORTER_OTLP_HEADERS the same way. The default protocol is http/protobuf. For HTTP, init() appends /v1/traces unless the endpoint already ends with that path.
metrics=False because the three tools below ingest traces. Leave logs alone: log export is off unless you pass logs=True. An application file applies the same class with pxt schema update instead of TableModel.create_all(). Creating the table and inserting rows are separate traces. The generation is on the insert, and on an update, and when a new computed column backfills rows that already exist. A later collect() is a pixeltable.collect span and no new model call, because the computed value is stored.
A script that exits should flush. init() uses a BatchSpanProcessor, which ships on a timer while the process stays up:
The same trace in Langfuse, Phoenix, and MLflow#
Nothing in the bridge is specific to a vendor. The endpoint and one header are the whole difference. Values below are the paths in each product's docs as of 2026-10-21. Pass the base URL to init(); it appends /v1/traces for HTTP.
| Backend | Endpoint for init() | Auth header |
|---|---|---|
| Langfuse | https://cloud.langfuse.com/api/public/otel (EU) or https://us.cloud.langfuse.com/api/public/otel (US). Traces are posted to /api/public/otel/v1/traces. HTTP only. | Basic auth, Authorization=Basic plus the base64 of public_key:secret_key. Keys are per project and per region. |
| Arize Phoenix | Self-hosted HTTP: http://localhost:6006. The collector is /v1/traces on port 6006, the UI port, not the generic OTLP port 4318. gRPC: http://localhost:4317 with protocol='grpc' and no path. The http:// scheme selects plaintext; without a scheme the gRPC exporter uses TLS. | Authorization=Bearer <PHOENIX_API_KEY>. Optional on a local server, required when that server has auth on. |
| MLflow | http://localhost:5000. The server exposes /v1/traces. MLflow 3.6.0 or newer, a SQL backend (SQLite, PostgreSQL, MySQL, or MSSQL), HTTP only. | x-mlflow-experiment-id=<experiment id>. When workspaces are on, add X-MLFLOW-WORKSPACE=<name>. |
Sources: Langfuse OpenTelemetry, Phoenix exporter and the Phoenix endpoint FAQ, and MLflow OTLP ingest. A remote Phoenix host is the hostname on its Settings page, with the same /v1/traces path. Pixeltable's own walkthrough of the bridge uses Grafana the same way: Observability.
For Langfuse, build the header in the process and run this before pxt_otel.init(). Do not write it into config.toml; it contains the secret key. A US project key on the EU host returns 401. LANGFUSE_HOST still works and is deprecated; use LANGFUSE_BASE_URL.
x-langfuse-ingestion-version=4 makes a direct OTLP export show up in real time. Without it, Langfuse says ingestion can lag by about 10 minutes. The screenshot below was recorded through the Langfuse SDK path in Pitfalls, with the insert wrapped in a Langfuse span named ingest-docs.

pxt.* attributes on the selected span. Phoenix and MLflow take the same OTLP payload; this post has no screenshots of them.gen_ai and OpenInference, in plain terms#
Two vocabularies describe a model call, and they are not the same attributes.
gen_ai is the OpenTelemetry GenAI semantic convention. A model-call span carries gen_ai.request.model, gen_ai.usage.*, and the prompt and completion under gen_ai.input.messages and gen_ai.output.messages. Older instrumentations write the deprecated gen_ai.prompt and gen_ai.completion. The Anthropic Python SDK 2.0.0 we tested emits these spans itself, as anthropic.messages.create, with no extra instrumentor. It records message content only when its traces content_mode is content; the default is metadata_only. Langfuse showed those spans as generations, with cost.
OpenInference is Arize's vocabulary for LLM apps. A model call's span kind (openinference.span.kind) is LLM. Tokens are llm.token_count.*. The prompt and completion are input.value and output.value. openinference-instrumentation-openai writes that, and it is what we tested under pixeltable.udf.chat_completions.
Who reads which:
- Langfuse maps both into one generation. Its OTEL attribute table accepts
gen_ai.*attributes, includinggen_ai.usage.*, OpenInferenceinput.valueandllm.token_count.*, andmlflow.spanInputs. Pixeltable'spxt.*spans still appear in the tree; they are ordinary OTLP spans. The Langfuse SDK's default filter would have dropped them. See the pitfalls below. - Phoenix is built around OpenInference, so the generation view is that child span. The Pixeltable tree arrives with it, because the collector accepts any OTLP trace.
- MLflow stores the OTLP spans you send. Its own SDK speaks
mlflow.*and can emitgen_ai.*on the way out whenMLFLOW_ENABLE_OTEL_GENAI_SEMCONVis set. For a Pixeltable trace, read the span tree in MLflow. The GenAI columns fill in when the child span speaksgen_ai.*, which the Anthropic SDK did in our test. OpenInference attributes stay on the span as attributes.
Do not attach two instrumentors to the same provider. In our Anthropic test, the SDK's native spans plus openinference-instrumentation-anthropic produced a second generation for every call and double-counted cost. OpenAI needs the OpenInference instrumentor for a generation: Pixeltable records token counts as an event on the UDF span, and the backends do not show that event as a generation. Other OpenInference or OpenLLMetry instrumentors that attach to the global provider should nest the same way. We tested OpenAI and Anthropic.
Files and frames#
span_level is a threshold: info, debug, or trace. The docstring on init() matches the call sites.
| Level | What you get |
|---|---|
info (default) | The operation span, plus catalog, store, and SQL work: pixeltable.catalog.begin_xact, pixeltable.sa.insert_rows, pixeltable.store.insert_rows, pixeltable.store.write_column, pixeltable.view_load, metadata writes. |
debug | Adds pixeltable.row, pixeltable.udf.<name>, per-file spans, and the finer catalog and store spans such as pixeltable.plan.create and pixeltable.store.build_rows. |
trace | Adds one span per iterator step, named pixeltable.iter.<iterator>. A frame_iterator step is one decoded frame. |
Per-file spans, all at debug:
pixeltable.media.fetch, one per downloaded file, and only on a cache miss.pxt.urlis set at the start with userinfo, query, and fragment stripped, because a presigned URL carries credentials.pxt.bytesis attached when the download succeeds.pixeltable.media.encode, one per generated file written to a temp file.pixeltable.media.save, one per persisted file, withpxt.bytes, andpxt.destinationwhen the column uses a configured store. It is left out for the default store.
There is a cap, and it is narrow. ExprEvalNode.MAX_ROW_SPANS is 100. Each expression-evaluation node opens at most 100 pixeltable.row spans per operation, and only for rows whose parent_row is unset. Rows past that still run. A UDF span that nests only under the row span is skipped with it. A call that went through a resource-pool scheduler still emits its pixeltable.udf.* span at debug, beside the row span, with pxt.resource_pool and pxt.retries. Iterator spans have no cap in the source. span_level='trace' on a long video is one span per frame. Use debug unless you are inspecting the iterator itself. info drops the row and UDF spans, so on an insert the generation's parent is pixeltable.store.insert_rows.
At debug, each sampled row has a pixeltable.row span and a pixeltable.udf.resize span, and each file that had to be fetched or saved has a media span. At trace, each decoded frame adds pixeltable.iter.frame_iterator around that step. The first 100 rows of the evaluation node get the row span; the iterator spans keep going for every frame.
Lineage stays. The trace is optional.#
Your Agent Needs a Data Plane, Not a Dashboard makes a specific objection: almost every route to a pretty timeline asks you to ship traces, prompts, and user payloads to a vendor. That objection is about the trace, and it is right. It does not describe the catalog. Pixeltable does not turn telemetry on by itself. The bridge is a separate install, and pxt_otel.init() exports nothing until you configure an endpoint or attach it to a provider you set up. Rows, computed values, and column lineage stay under PIXELTABLE_HOME whether or not a span leaves the process. You choose the receiver: Langfuse, a Phoenix you run, MLflow on your machine, or a collector that redacts before anything crosses the network. The session log and the dependency graph remain the system of record. The span tree answers the question lineage does not: which attempt, which file, which retry, how long.
That split is also the observability layer in The Invisible 80%. Lineage, version history, and reproducibility come from the computed columns. Trace ids, input and output capture, and a latency breakdown are the export you turn on here, with a retention policy you set on the collector, not a second copy of the database.
Pitfalls#
- The Langfuse SDK drops Pixeltable spans by default. This applies when the Langfuse client is your tracer provider. Since SDK v4,
should_export_spankeeps Langfuse spans,gen_ai.*spans, and known LLM-instrumentor spans. Pixeltable's scope name ispixeltable, so its spans are filtered out. Create the client first, widen the filter, and attach withPixeltableInstrumentor.pxt_otel.init()is not needed here: it would reuse the client's provider and add no exporter. Flush withlangfuse.flush().
- Noise. With the bridge on,
create_dir,create_table,drop_dir, andcollectare traces too.span_level='info'keeps the operation and the INFO work spans and drops the per-row detail.
What leaves the process#
Prompts and completions travel on the LLM child span, to whatever endpoint you set. Pixeltable's log export is off by default. Leave it off. Log records can carry API keys in error messages, signed URLs, and connection strings. If you do enable logs=True, or if you want prompts redacted before they reach a vendor, do that in an OpenTelemetry Collector in front of the backend. The fetch span already strips credentials from pxt.url. The header that authenticates the exporter contains a secret; keep it in the environment, or on a hosted database run pxt secret set pxt://<org>:<db> OTEL_EXPORTER_OTLP_HEADERS=... and then pxt service restart (see Configuration), not in a file you commit.
See also#
- Observability in the Pixeltable docs, including the span tree and the metric names
- What is a declarative pipeline?
- The Invisible 80%, where lineage is the observability you get from the schema
- Your Agent Needs a Data Plane, Not a Dashboard
- Langfuse OpenTelemetry, Phoenix OTLP, MLflow OTLP ingest